Azure Blob Storage Prerequisites
Configure your Azure Blob Storage destination.
Prerequisites
- If your storage account restricts network access, have our data syncing service's static IP (
34.171.168.215/32) available. It will be required in Step 1.
Step 1: Create Azure storage account
- In the Azure portal, navigate to the Storage accounts service and click + Create.
- In the "Basics" tab of the "Create a storage account" form, fill in the required details.
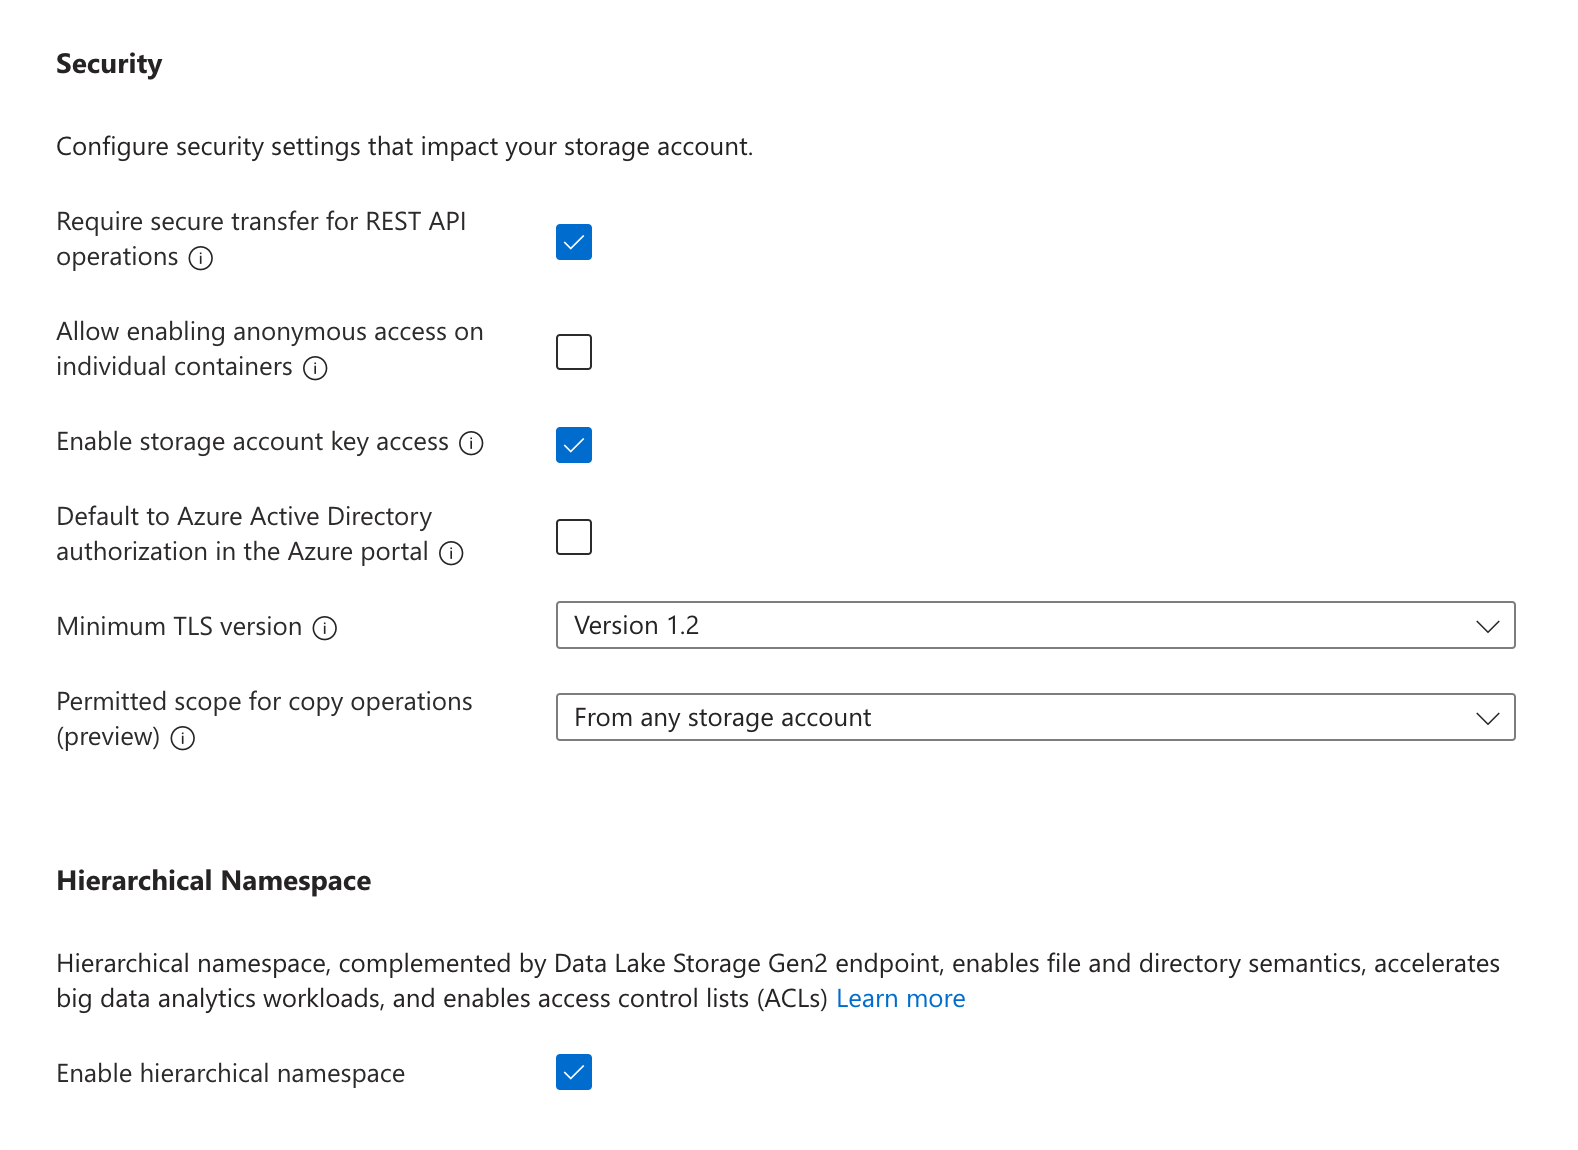
- In the "Advanced" settings, under "Security" make sure Enable storage account key access is turned on. You may turn off (deselect) "Allow enabling public access on containers". Under "Data Lake Storage Gen2", select Enable hierarchical namespace.
- In the "Networking" settings, you may limit "Network access" to either Enable public access from all networks or Enable public access from selected virtual networks and IP addresses. If the latter is selected, be sure to add our static IP (
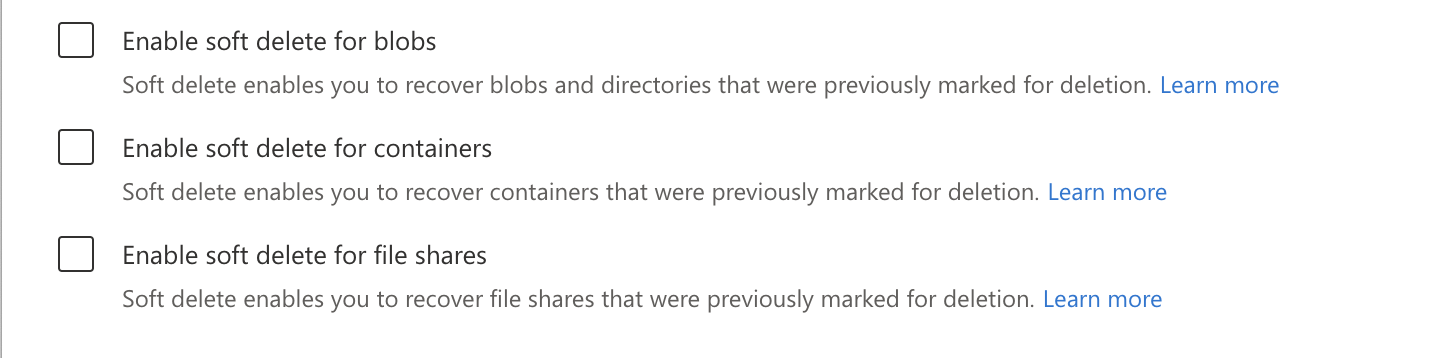
34.171.168.215/32) to the address range of the chosen virtual network. All other settings can use the default selections. - In the "Data protection" settings, you must turn off Enable soft delete for blobs, Enable soft delete for containers, and Enable soft delete for file shares.
- Once the remaining options have been configured to your preference, click Create.
Step 2: Create container and access token
- In the Azure portal, navigate to the Storage accounts service and click on the account that was created in the previous step.
- In the navigation pane, under "Data storage", click Containers. Click + Container, choose a name for the container, and click Create.
Recommendation: dedicated container for data transfersUse a unique container for these transfers. This:
- Prevents resource contention with other workloads
- Avoids accidental data loss from mixed lifecycle or cleanup rules
- Improves security by reducing surface area and enabling tighter, destination-scoped policies
- In the navigation pane, under "Security + networking", click Shared access signature.
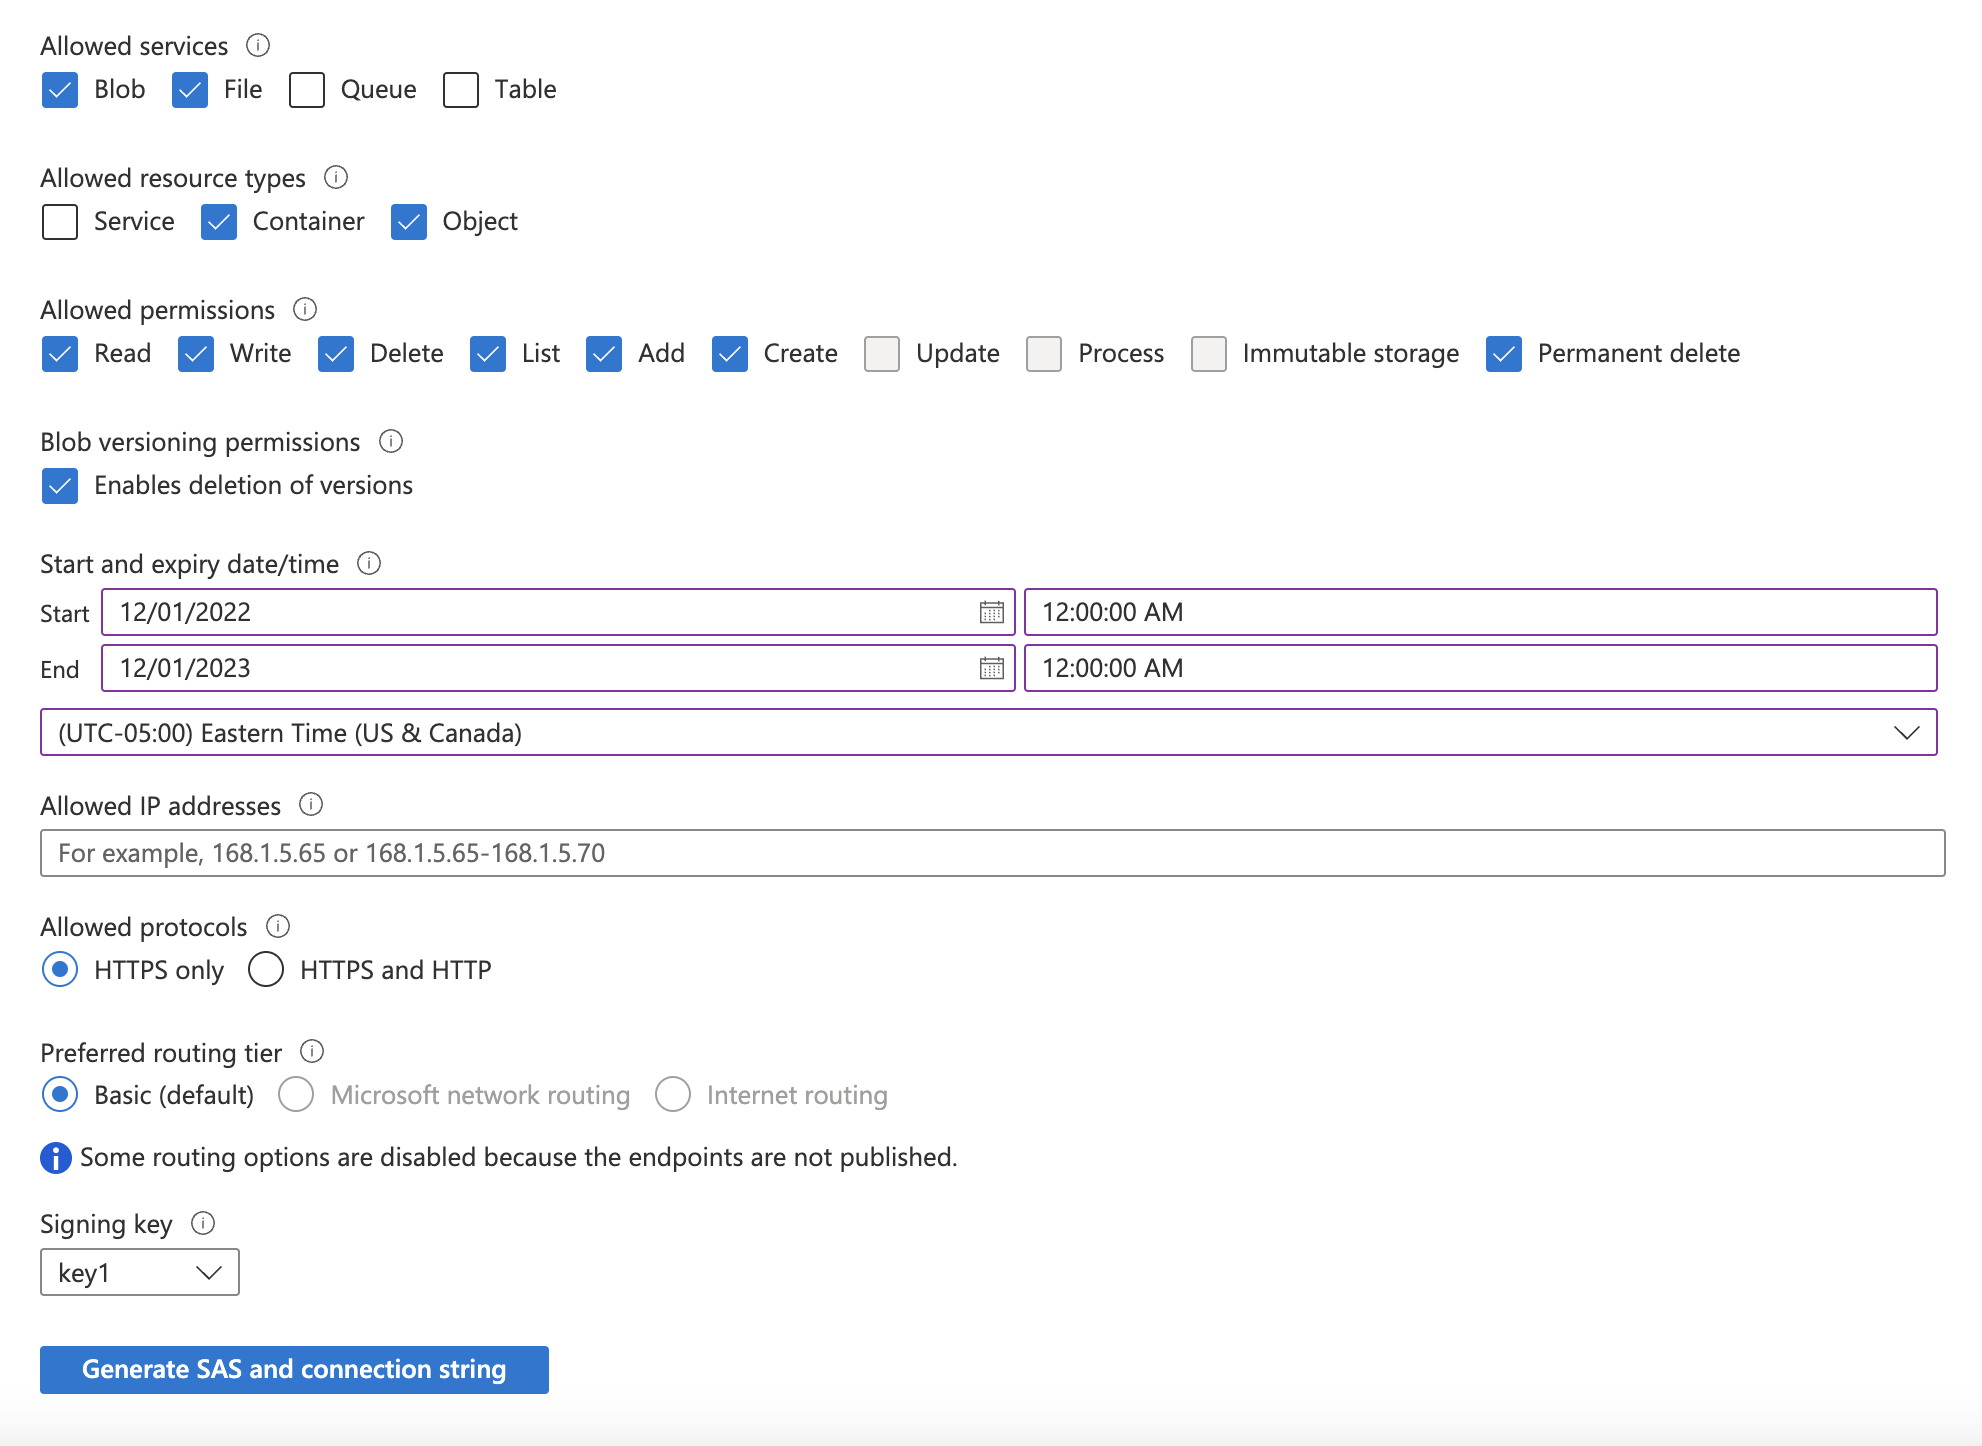
- Update the required accessible services and permissions:
- Under "Allowed services": select Blob and File.
- Under "Allowed resource types": select Container and Object.
- Under "Allowed permissions": select Read, Write, List, Add, and Create (optionally select Delete and Permanently Delete if you wish to let connection tests automatically clean up test files).
- Select a "Start and expiry date/time" based on your security posture (e.g., set the expiration date 6 months into the future), and click Generate SAS and connection string.
- Make a note of the SAS token that is generated.
Connection Test File Cleanup (Optional)By default, a connection test is performed against the destination during initial configuration. This test writes temporary artifacts under the prefix
_test_connection/(located at either the container root, or inside the custom folder prefix configured on the destination, if present).If you do not grant delete permissions (Delete and Permanently Delete), the connection test will still succeed, but these test files will remain in your container. To automatically clean them up and avoid clutter or minor storage charges, you can optionally configure an Azure Lifecycle Management rule on your storage account to delete blobs matching the prefix
_test_connection/(or<your_folder>/_test_connection/if a custom folder was configured) after 1 day, or delete them manually.
Step 3: Gather the required setup information
For the data export setup, you will need:
- Storage account name
- Container name (entered in the Bucket name field)
- Folder name for the exported data
- SAS token
Visit the LogRocket Streaming Data Export settings page to complete the setup.
FAQ
Q: How is data organized in the container?
A: Data lands in Hive-style partitions per model: <folder>/<model_name>/dt=<transfer_date>/<file_part>_<transfer_timestamp>.<ext>. To write to the container root, enter . as the folder name.
Q: How do I know when a transfer completed?
A: Each transfer writes a manifest file per model under _manifests. Files are written per model per transfer in the format: _manifests/<model_name>/dt=<transfer_date>/manifest_{transfer_id}.json.
Q: Why do I sometimes see duplicates?
A: Object storage is append-only. The change detection process uses a lookback window to ensure no data is missed, which can create duplicates. Downstream pipelines should deduplicate on primary keys prioritizing the most recent transfer window; manifest files can help bound the set of files to read.
Q: Are there file size limits?
A: No explicit size/row limits for Blob Storage; files are split automatically based on volume and performance heuristics.
Updated about 3 hours ago
What’s Next
Learn about how to configure the Streaming Data Export integration in app!